Featured Projects
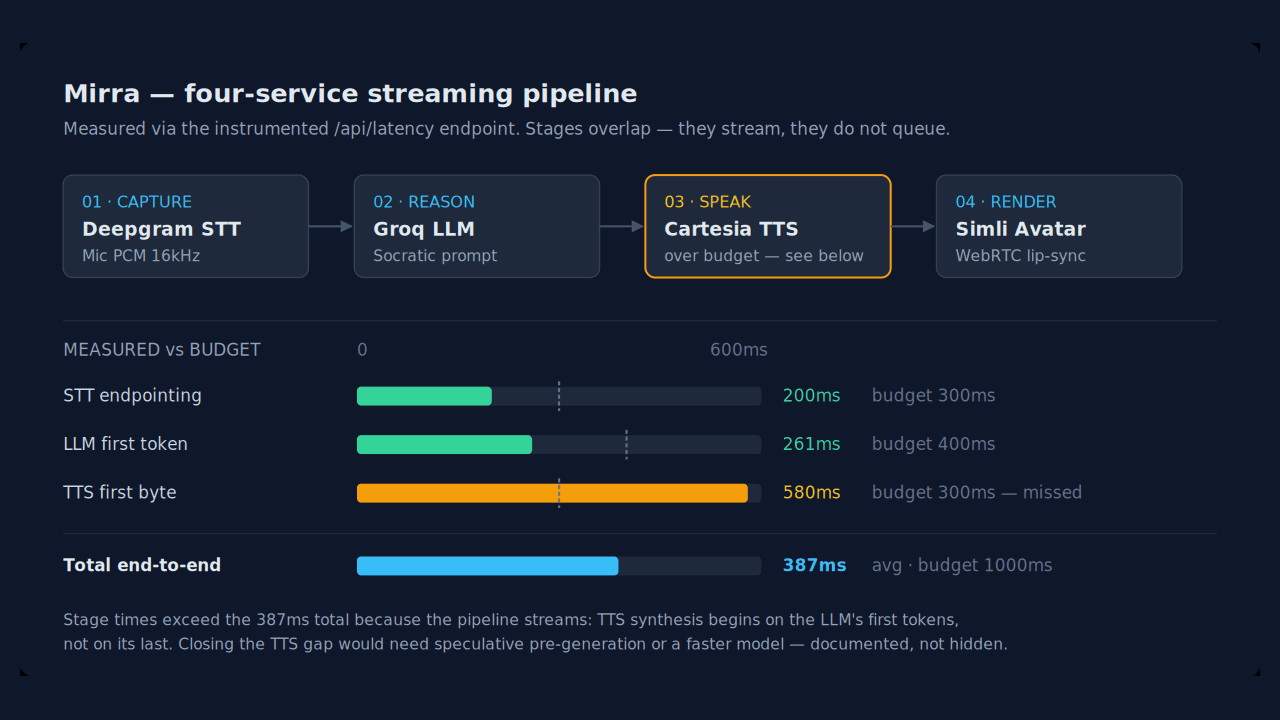
Mirra — Real-Time AI Video Tutor
A four-service streaming pipeline — Deepgram STT to Groq inference to Cartesia TTS to a lip-synced Simli avatar — running at ~387ms end-to-end over WebSocket and WebRTC. The engineering was backpressure, stream teardown and keepalive handling, not prompting. Latency is measured by an instrumented endpoint, not estimated.
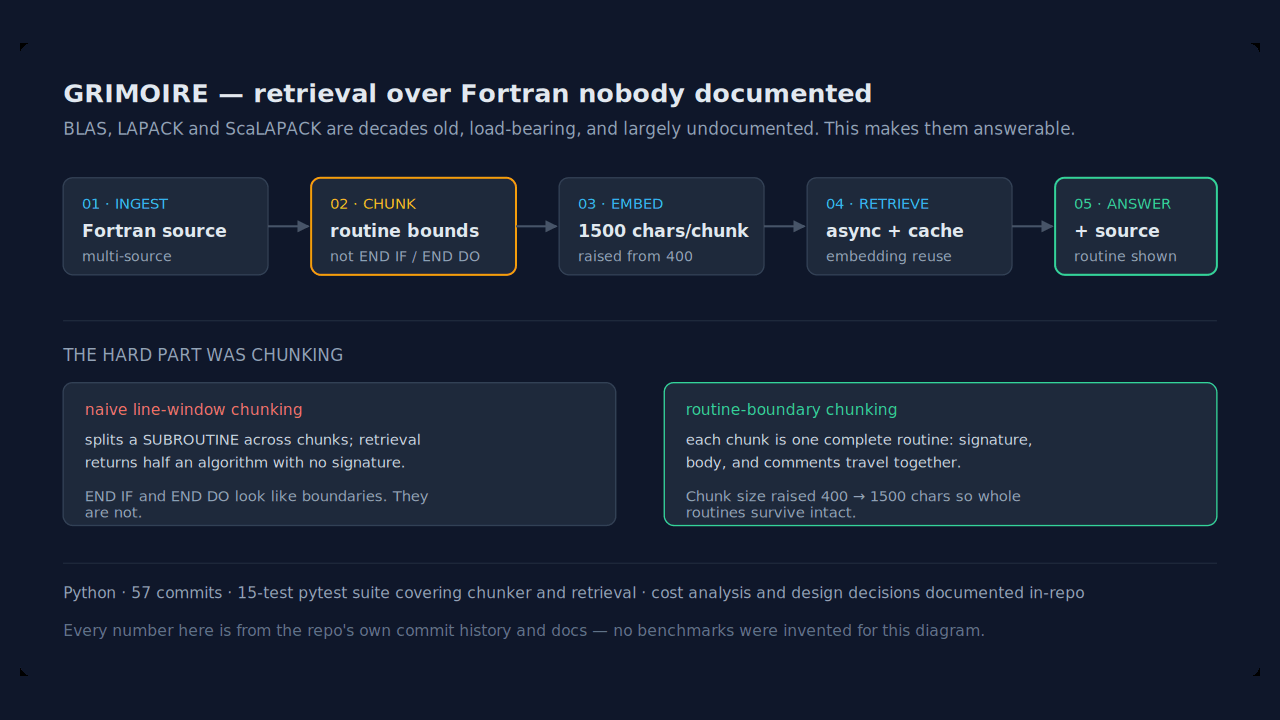
GRIMOIRE — RAG over Legacy Fortran
Makes BLAS, LAPACK and ScaLAPACK codebases queryable in natural language. The hard part was chunking: naive line windows split a SUBROUTINE in half and return an algorithm with no signature, so chunks are cut on routine boundaries instead. Python, 15-test suite covering the chunker and retrieval.

Prometheus Talent Engine
AI-powered talent retention platform that uses predictive analytics to identify at-risk employees and provide actionable retention recommendations. Built to demonstrate ethical AI that enhances human employment rather than replacing it.
Experience Highlights
Testing & QA
- 90% test coverage achievement
- Jest and Cypress expertise
- React Testing Library mastery
- CI/CD integration
Development
- React & TypeScript
- T3 Stack proficiency
- State management expertise
- Performance optimization